CASE meyco3VISION
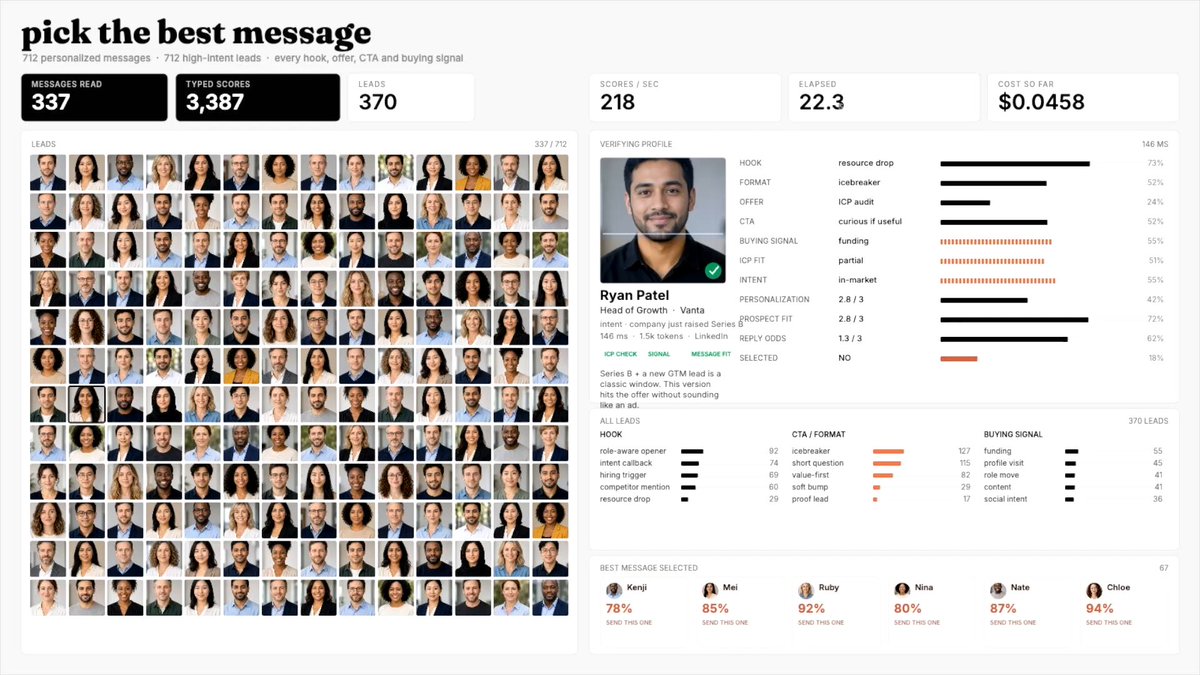
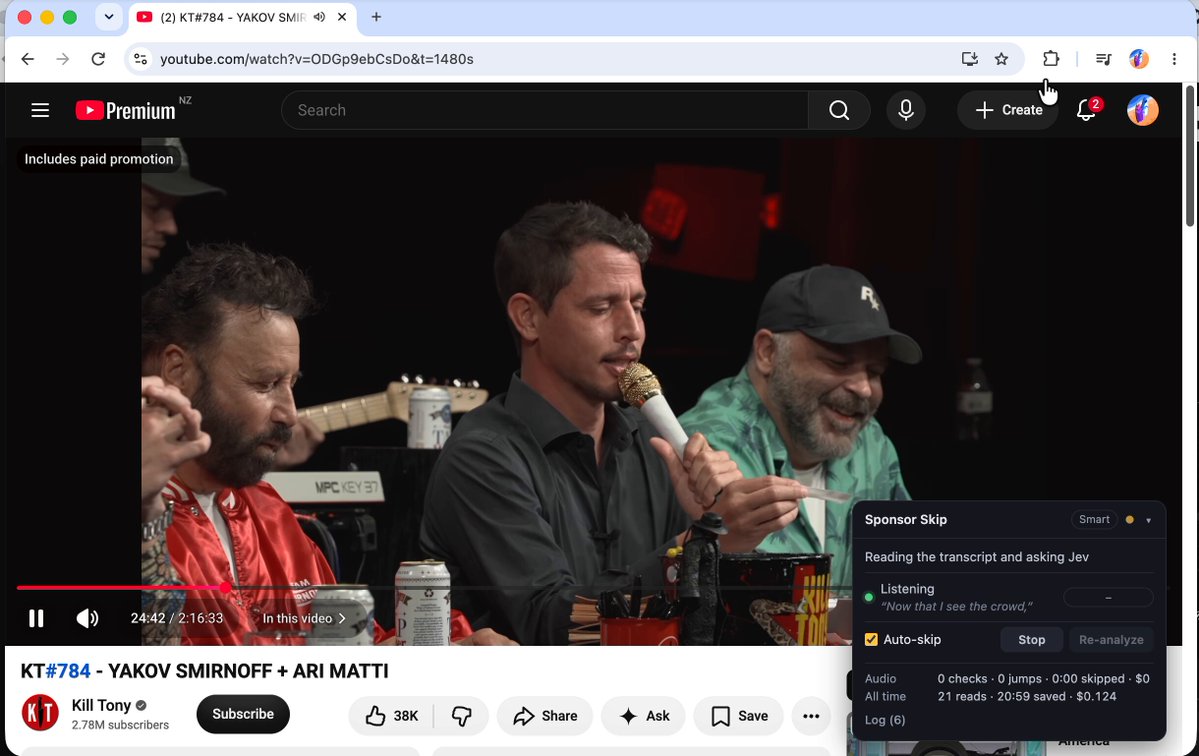
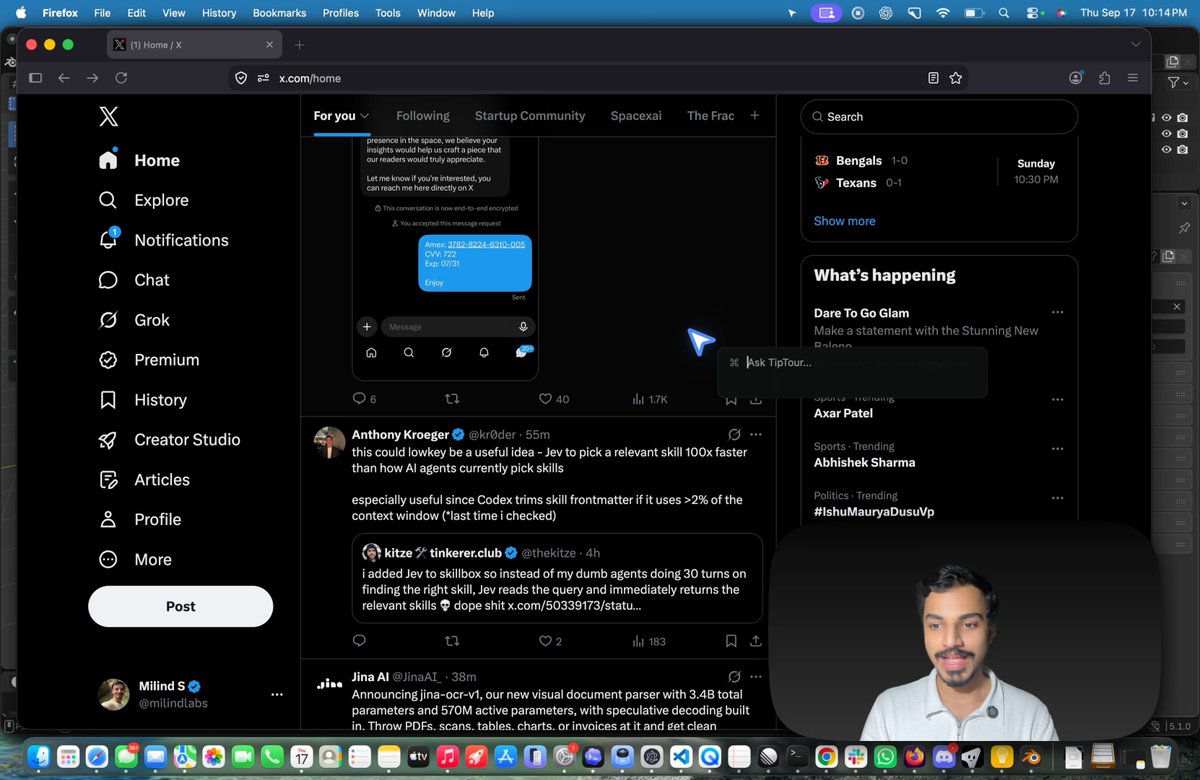
Okay so Jev can actually do computer use really well
Without any screenshots, or LLMs and no Pixels leave my mac
I dont even read the Dom elements
A local CoreML model segments every button and UI element on screen.
On-device OCR reads the labels. That text is all Jev gets.
It returns a probability across those elements and tells me the best one to click.
Then it clicks, re-runs detection, and decides again. In a loop until the goal is done.
~90ms per decision. Faster than any LLM computer use I've tried.
Blazing fast computer use, without any latency
@typesafeai is building something really interesting翻訳
なるほど、Jev は computer use を本当にうまくやれる スクリーンショットも LLM も使わず、ピクセルは 1 枚も自分の Mac から出ない DOM 要素すら読んでいない ローカルの CoreML モデルが画面上の全ボタンと UI 要素を切り出す。 端末内の OCR がそのラベルを読む。Jev が受け取るのはそのテキストだけ。 Jev はそれら要素にまたがる確率を返し、押すべき最適なものを教えてくれる。 そしてクリックし、検出をやり直し、また判断する。目的が達成されるまでループで。 1 判断あたり約 90 ミリ秒。自分が試したどの LLM の computer use より速い。 遅延のない、猛烈に速い computer use だ @typesafeai は本当に面白いものを作っている
111.6K
再生
1.6K
いいね
1.4K
保存
85
リポスト
引用元の投稿
Diogo Almeida @CompleteSkeptic
After co-inventing ChatGPT, I kept asking myself: why have superhuman chat models not led to AGI? I’ve spent the last 2 years in stealth building a new way to train models (RLCD), and a new type of frontier AI model that we are releasing today: Jev • 20-200x faster • 40-400x https://t.co/JSybNG2BKJ
34.6M 再生元の投稿 ↗
リンクとタグ
@typesafeai
Sep 18, 2026, 7:26 PM に収録
視覚の事例をもっと見る